Professor of Language, Communication and Computation at Utrecht University.
a.p.j.vandenbosch@uu.nl
visiting Utrecht University, Faculty of Humanities
Trans 10
3512 JK Utrecht
The Netherlands
postal Utrecht University, Faculty of Humanities
P.O. Box 80125
3508 TC Utrecht
The Netherlands
I study how computers learn to handle language.
My group builds the kind of AI that powers chatbots like ChatGPT,
but we also ask ourselves: can we make it greener, more honest about
where its answers come from, and easier for society to govern?
On this page you'll find my current research, a few reads,
the software we created, the projects we run, and the people I work with.
For the formal record, see
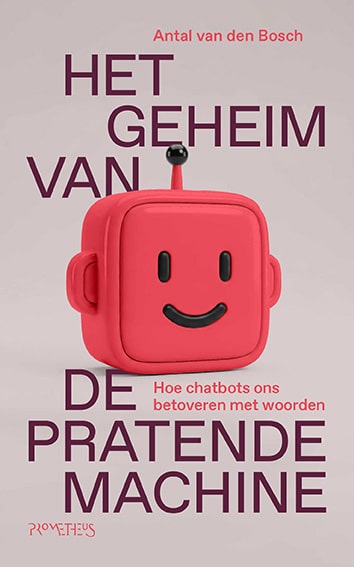
In October 2026, Uitgeverij Prometheus publishes my
new book (in Dutch) Het geheim van de pratende machine: Hoe chatbots ons betoveren met woorden
(The secret of the talking machine: how chatbots enchant us with words).
It explains, for a general audience, how chatbots work — brilliant, helpful imitators
that predict the next word without understanding it — and traces the idea from the
Second World War to today's language models.
New publication: Memory-based speculative decoding
Speculative decoding lets a large language model generate text faster by having a
small "draft" model guess ahead. In this new paper the draft model is not a neural
network at all but Olifant, our memory-based model. The result: on legal text,
generation is up to 2.4× faster and uses 2.5× less energy per token, with identical
output. The three-minute animation below shows how it works, without and with a
key–value cache.
Towards Green Text Generation: Memory-Based Speculative Decoding.
Antal van den Bosch. To appear in the Proceedings of INLG 2026.
Code: github.com/antalvdb/olifant-speculative.
What I work on
At heart, my research is about one deceptively simple task: predicting the next word.
That is the trick at the core of every modern language model, including ChatGPT.
It sounds mundane, but it turns out you can squeeze an astonishing amount of language,
reasoning and culture out of a really good next-word predictor.
My work sits at the intersection of machine learning — teaching computers from
examples — and language. The models we build are useful in their own right,
but they also speak to deeper questions in linguistics, psychology and neuroscience
about how humans handle language. I particularly enjoy projects that cross disciplines.
Olifant: a lighter alternative to ChatGPT-style AI
Today's chatbots are built on Transformers, an architecture that is powerful
but extremely hungry for electricity. With Maarten van Gompel, Peter Berck, Ko van der Sloot
and a growing team of students, I am reviving an older, simpler idea — memory-based
language models — and showing it can do much of the same work for a fraction
of the energy.
The numbers are dramatic: training our models uses roughly 1,000× less electricity
than training a Transformer of similar capability, and answering questions costs
10 to 100× less. They scale up nicely when given more data, and — unlike
mainstream language models — they can tell you which examples from their training
data a given answer is based on. That is a feature, not a bug: it makes the model's
behaviour easier to inspect and trust.
We released the software as Olifant
(Dutch for "elephant"), wrote up the method in a paper,
and are sharing demos and downloadable models.
From the Olifant paper: estimated CO2
emissions (measured with CodeCarbon) for letting different language models predict the next words
in a 500,000-token text. The dashed reference lines show everyday emissions for comparison
— a washing-machine run, ten minutes of driving, a litre of milk. Two of our models
stay well below the washing machine, while larger GPT-style systems climb steeply.
Try it yourself: the demo below shows, for any sentence you type,
which earlier examples Olifant is drawing on to predict the next word.
There's also a text generation demo
and a collection of Olifant models
on Hugging Face.
Advising on AI policy
Because I build these systems, I am often asked what to do about them.
With colleagues Fabian Ferrari
and José van Dijck I advise
governments and academic bodies on how generative AI should be regulated.
Sensible policy needs both the technical and the governance side at the table.
Read more in the
UU news item
or in our Nature Machine Intelligence paper.
Cultural AI is a lab for "culturally aware" AI —
AI systems that take seriously how subtle, plural and contested human culture is,
rather than flattening it.
With Walter Daelemans I wrote
Memory-based language processing
(Cambridge University Press, 2005), which lays the groundwork for the Olifant line of research.
This course introduces students to the Transformer — the T in GPT —
the workhorse architecture that, since ChatGPT was released in late 2022, has reshaped
AI overnight. At its core the Transformer does just one thing: predict the next word.
So how does a next-word predictor pass exams? How does it appear to reason?
Where does it fail, and where is the field heading next? Those are the questions we work through.
Public talks
In the Netherlands and Belgium, newly appointed professors traditionally give a
public inaugural lecture. I have had the privilege three times — at Tilburg (2008),
Radboud Nijmegen (2012), and most recently at KU Leuven KULAK
in 2023, when I held the
Francqui Chair on Language and AI.
All three talks circle the same surprising idea: predicting the next word
is enough to get you a long way. Already in 2008 I argued that next-word predictors
just keep getting better the more text you train them on — ten times more
data buys you a steady, predictable bump in accuracy. That observation
(Heaps' Law, if you want the technical name)
quietly underlies the entire boom in large language models we are living through.
Het volgende woord — Tilburg University, October 2008. Some animations on YouTube; below, a small one showing Dutch sentences where the next word is essentially fixed.
Affiliations
Since September 2022 I have been professor of Language, Communication and Computation at the
Faculty of Humanities,
Utrecht University.
Since July 2023 I serve on the Board of NWO, the Dutch Research Council,
as domain chair for Social Sciences and Humanities.
I am a guest professor at CLiPS,
University of Antwerp.
Beside papers, our projects produce software. Where we can, we release it under
open-source licenses; some packages also run as
webservices with a friendly interface,
and several have been folded into national and European research infrastructure.
A few highlights:
Olifant — the memory-based
language model from the left column. Built on a long line of earlier work, including
the WOPR system from 2010 that — with much less data and far smaller computers —
already predicted next words for fun.
With Peter Berck, Maarten van Gompel, Ko van der Sloot, Teun Buijse and Ainhoa Risco Paton.
Frog — an all-in-one tool for analysing Dutch text:
it identifies parts of speech, finds word stems, and untangles sentence structure.
With the Frog development team.
T-Scan
(also a web tool) — analyses Dutch text
for features that correlate with reading difficulty.
Timbl — the Tilburg Memory-Based Learner.
The classic machine-learning toolkit that powers much of our memory-based work.
With Ko van der Sloot, Walter Daelemans and Jakub Zavrel.
More software and digital infrastructure
Natural language processing
Valkuil.net and
Fowlt.net — context-sensitive spelling correctors
for Dutch and English.
Colibri Core —
efficient n-gram and skip-gram modelling. With Maarten van Gompel.
Mbt — memory-based
part-of-speech tagger. With Ko van der Sloot, Jakub Zavrel and Walter Daelemans.
WOPR in 2010 generating "word salad" — what a tiny precursor to ChatGPT looked like.
Digital research infrastructure
CLARIAH — Common Lab Research Infrastructure for the Arts and Humanities.
Nederlab — brings together digitised Dutch texts from the Middle Ages to today in one searchable interface (funded by NWO).
FutureTDM — a Horizon 2020 action on text and data mining.
TwiNL — a Netherlands eScience Center project with Erik Tjong Kim Sang.
ISHER — Integrated Social History Environment for Research.
Past projects
Show research projects I previously led or co-led
ADNEXT — Adaptive Information Extraction over Time, part of the COMMIT programme.
Ubisoft released the brain-training game
My Word Coach (Dutch)
for Nintendo DS and Wii. I did the background work on the Dutch localisation
together with Walter Daelemans (Antwerp).
April 2008.